OpsDesk Workforce
A self-hosted replica of care-home rota and staffing software, built as an RL environment for computer-use and tool-use agents. UK and German editions.
Watch an agent work
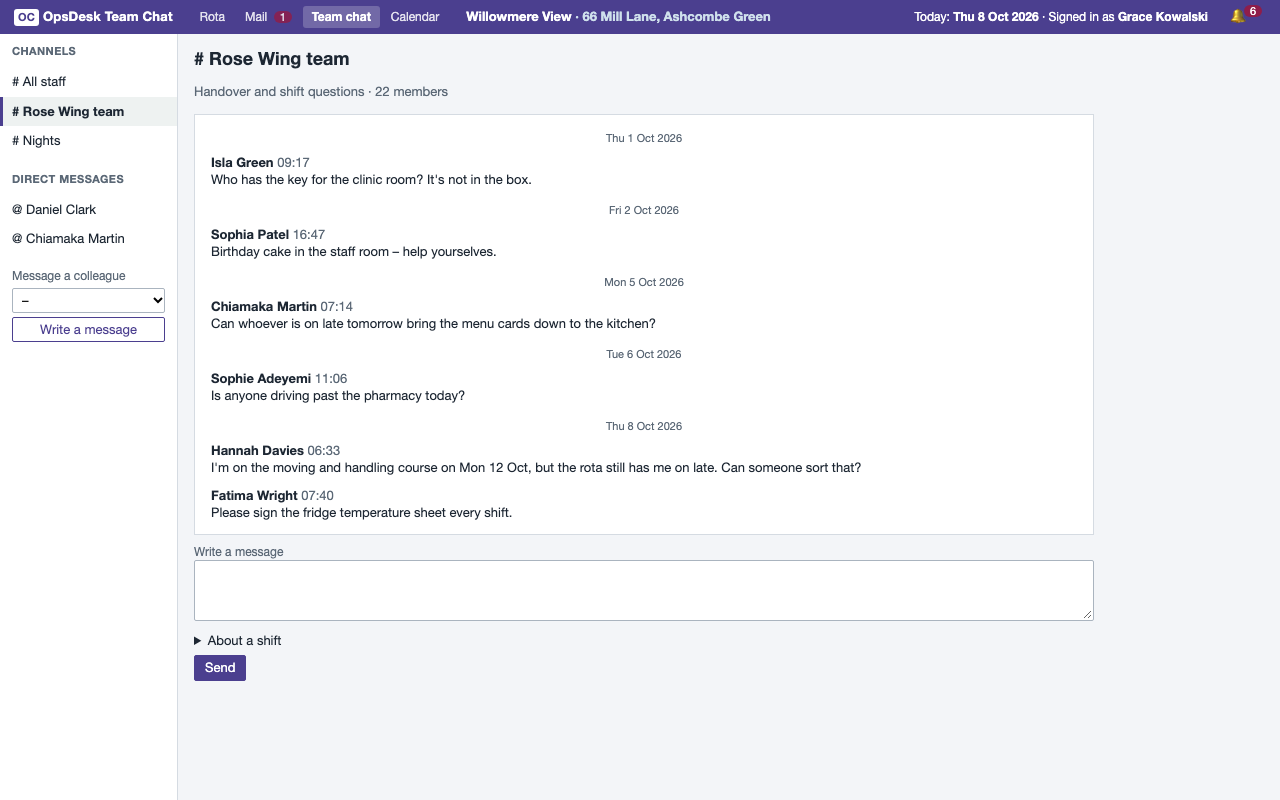
The agent covers a sick call and a course day: it reads the training provider's mail, asks a colleague in the team chat and gets a reply, then publishes. Score 1.0.
Inside the workspace
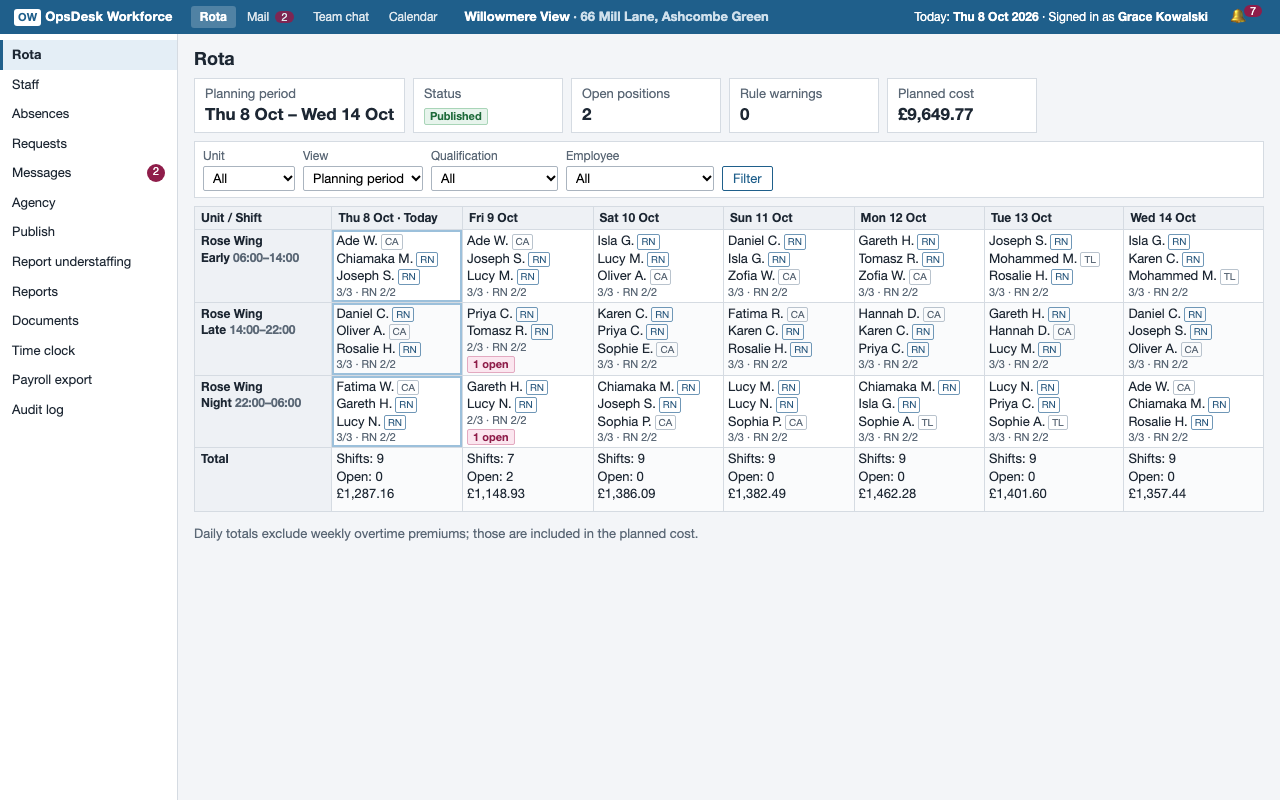
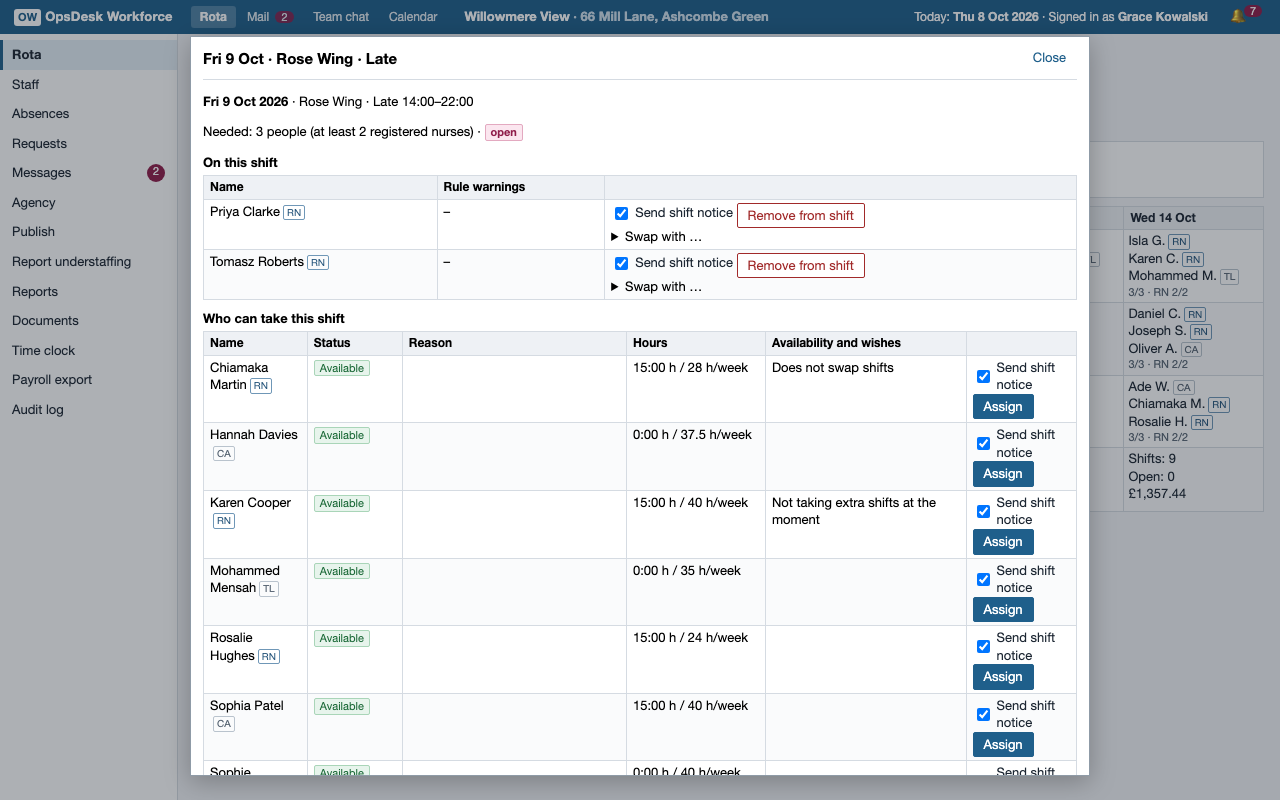
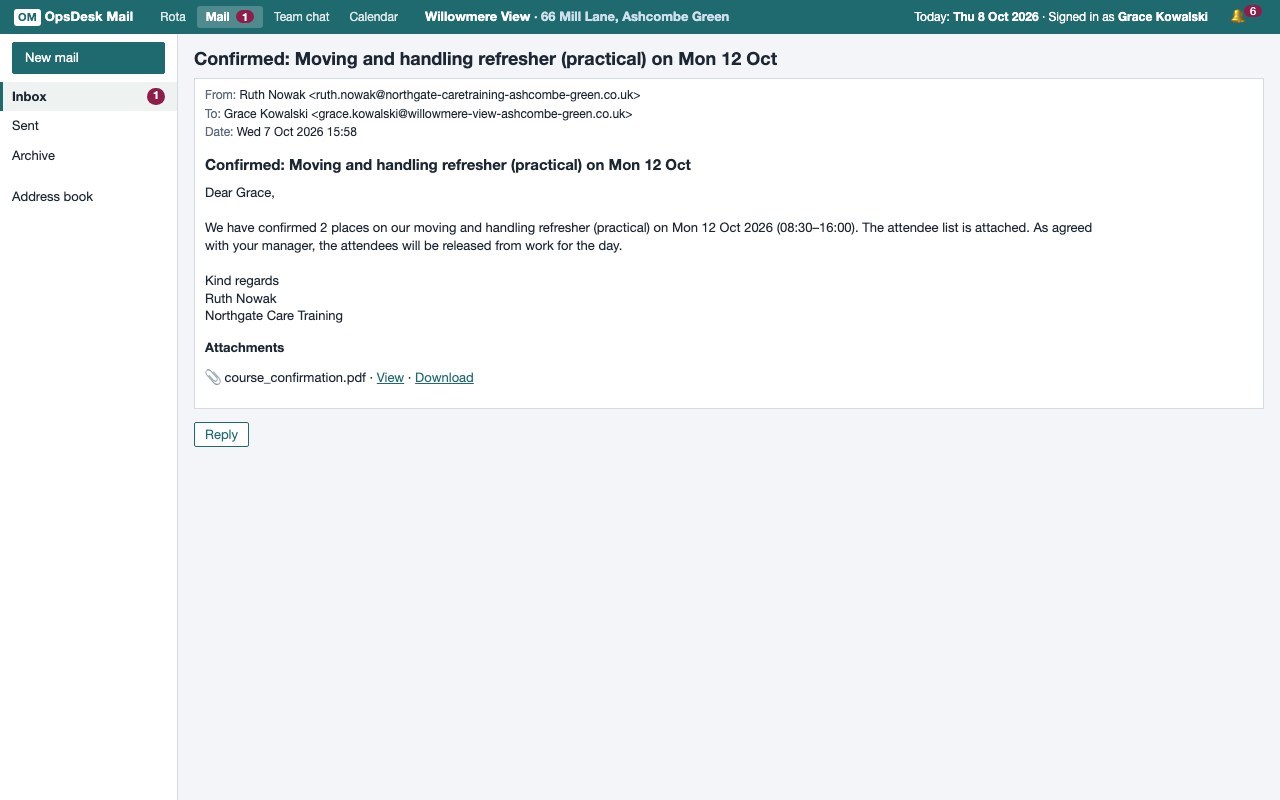
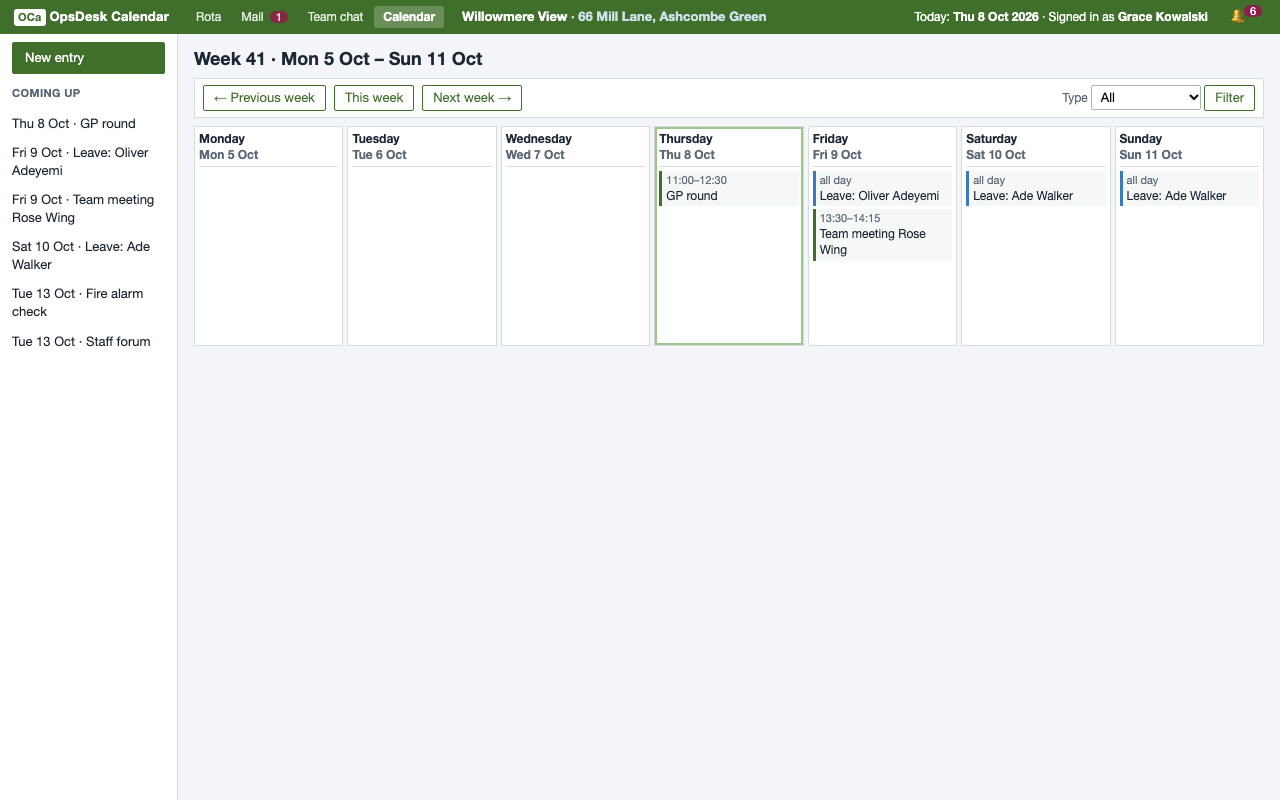
A workspace that answers back
-
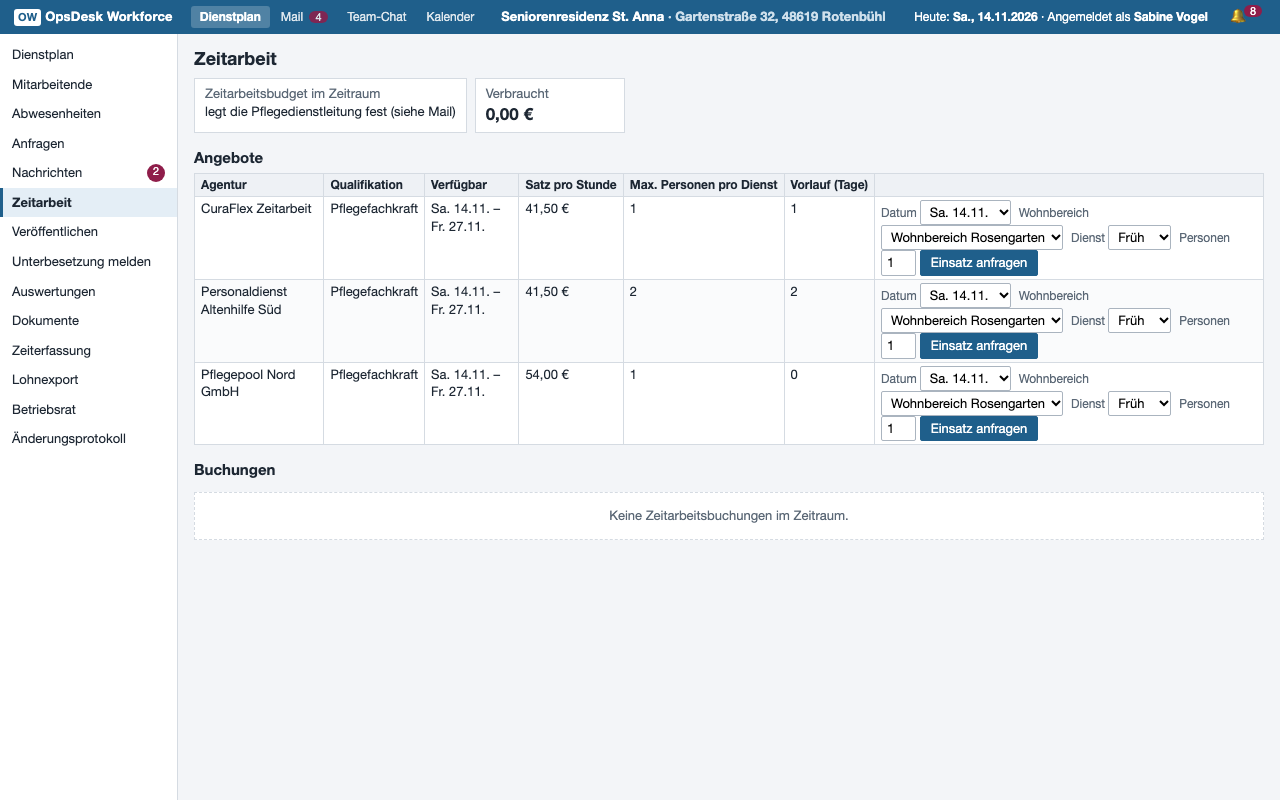
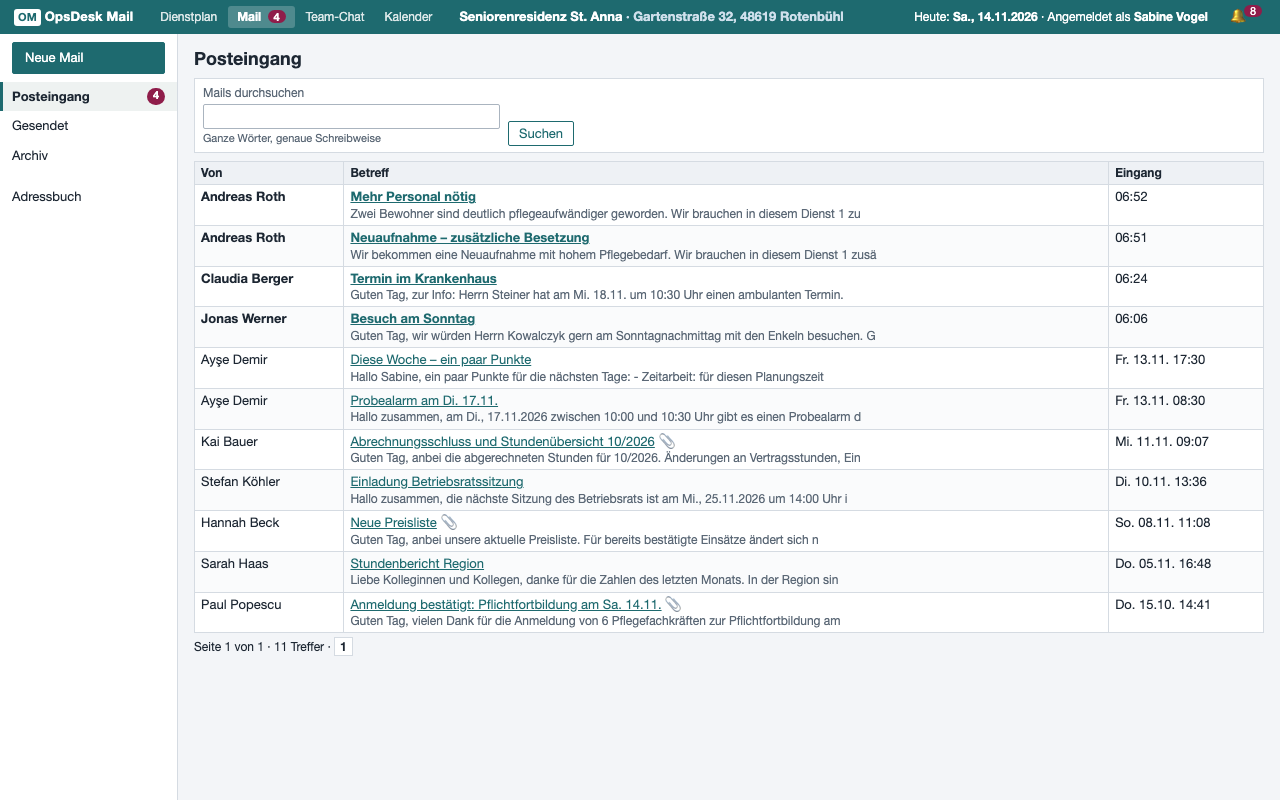
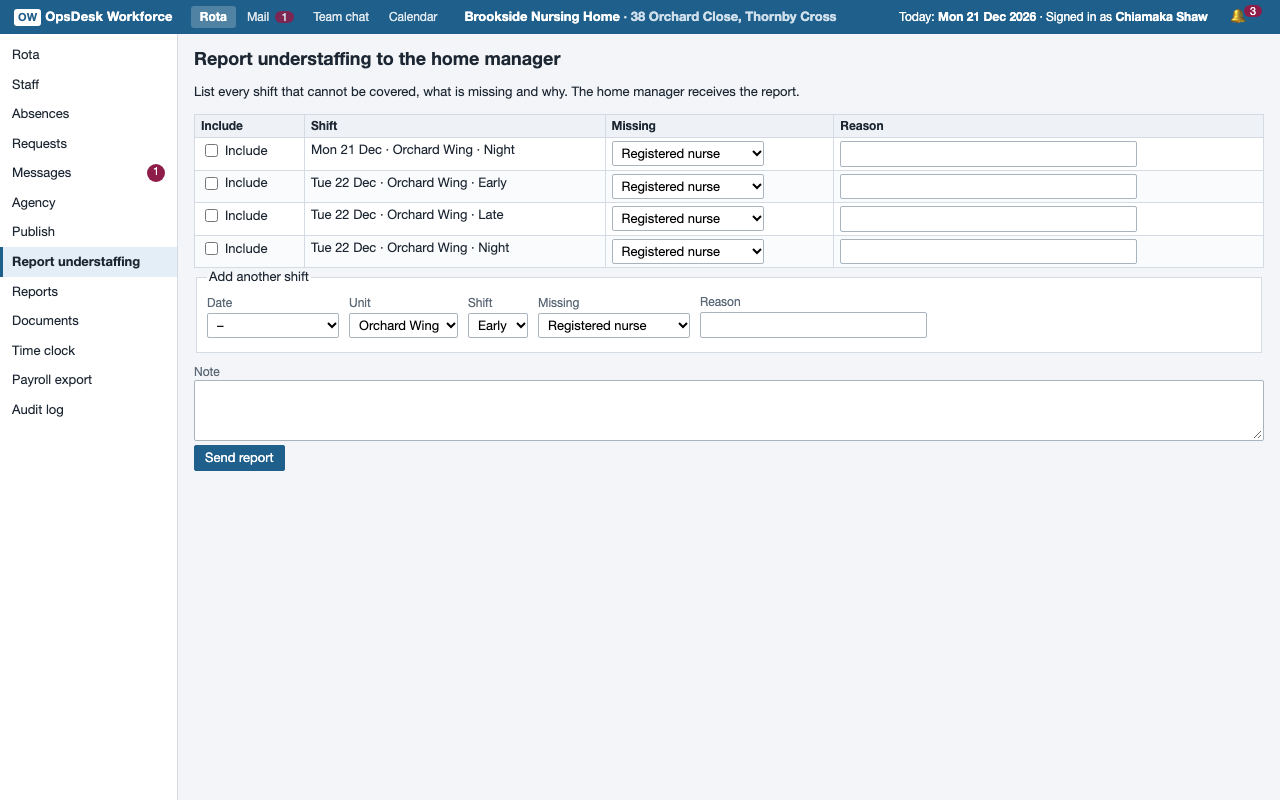
Four apps, one state: rota software (14 screens: rota, staff, absences, requests, messages, agency, publish, understaffing report, reports, documents, time clock, payroll export, works council and audit log), mail, team chat and calendar. The information an agent needs is spread across them.
-
Colleagues reply by fixed rules: staff, the home manager, agencies and the payroll office answer and decide. No model runs at run time.
-
Requests can change while the agent works, for example a second sick call or a withdrawn swap request.
-
Computer-use agents work in the browser GUI. Tool-use agents call the same functions over HTTP or MCP. Both change one shared state and produce identical results.
What agents do
| Request family | Example |
|---|---|
| Build a rota | Build a rota from a request, staffing needs and house rules. |
| Sick-call repair | Cover absences while preserving the rules and limiting changes. |
| Swap requests | Check swap requests against house rules and colleagues' wishes. |
| Demand increase | Cover increased staffing demand across the rota. |
| Bring the cost down | Reduce cost without breaking rules or changing unrelated records. |
| Answer the payroll office | Answer a payroll query from the time clock and exported data. |
| Works-council rejection | Repair a rejected rota in German homes. |
| Conflicting documents | Resolve conflicting records and documents. |
| Cover within an agency budget | Find agency cover within the stated budget. |
| Period that cannot be fully covered | Reach the proven maximum and honestly report what remains. |
Variants
-
Part of a request may appear only in the team chat or mailbox.
-
Training-provider mail and its PDF attendee list must be added to the calendar and rota.
-
A long-horizon tier spans 2–4 weeks and allows up to 462 actions.
How every result is checked
Gates · any failure scores 0
-
The final state is valid.
-
No hard rule is broken: UK Working Time Regulations or German Arbeitszeitgesetz, house rules, qualifications or absences.
-
No unrelated record is changed.
-
Coverage is complete, or reaches the solver-proven maximum where full cover is impossible.
Weighted layers
Cost
Compared with a frozen CP-SAT reference: full credit at or below it, zero at +10%.
Stability
Unforced changes are measured against the reference.
Messages
Every affected person is told; payroll replies are correct to the minute; courses include every attendee.
Honesty: claims made through the app, including publishing and understaffing reports, must match the final state. Any false claim scores 0. Any correct route gets full marks; the same final state always gets the same score.
Quality evidence
All evidence below comes from scripted agents, not models.
-
Gold agent scores 1.0 on every request via API, GUI forms and a real browser.
-
Seven cheating agents score 0 on every request.
-
0 of 557 near-miss solutions with exactly one thing wrong got full marks.
-
0 of 467 correct solutions using other routes or orders were rejected.
-
10 hack probes pass on every request; Harbor scoring runs in a separate verifier container.
-
GUI and API produce identical states; repeated runs are identical; exported action logs reproduce the final state.
-
Median reset is 10.4 ms; 40 containers on one machine are ready in 8.1 s, at 42 MiB each.
-
0 eval-signal hits across everything the agent can see.
-
Fresh, non-overlapping sets on demand: 100 new requests generated and fully verified in under 40 minutes on one machine.
Formats and data
-
Docker image, runs offline; snapshots, fast reset and JSONL action logs.
-
Harbor, HUD (computer use and MCP), OpenEnv, a verifiers-style task list, HTTP and MCP.
-
Fully synthetic data: no real personal data, third-party code, text, logos or product names.
-
10 request families for UK and German homes; long-horizon tier over 2–4 weeks, up to 462 gold actions.
-
About half the requests need two or more apps; easy to expert; 17–76 staff per home.
-
Fresh, non-overlapping sets per order. References stay host-side.
Licences and pricing
-
Evaluation: $12,000 for 50 new held-out requests; references stay with Vencur and exported episodes are scored. Fully credited to the first Program quarter if you start within 60 days.
-
Program: from $75,000 per quarter for at least two quarters; 500 new verified requests per quarter, delivered monthly. Each batch has a perpetual, non-exclusive licence.
-
One-time training set: $45,000 for the environment and 300 requests with references, perpetual licence, 90 days of support.
-
Exclusive licence: 4× the price.
-
Custom replica: from $40,000.
The sample is free; the $12,000 Evaluation is credited to your first Program quarter if you start within 60 days. The Program starts at $75,000 per quarter for at least two quarters, with 500 new verified requests delivered monthly. Each batch has a perpetual, non-exclusive licence; support alone is time-limited. The one-time training set is $45,000 and includes 90 days of support. Exclusive licences cost 4×. Invoices follow a 5-business-day check; unfixable defects are not billed.